July 15, 2026
CASE STUDY
July 15, 2026
xx min read

How Submission Prioritization Works in Modern Insurance Underwriting

Submission prioritization is the process insurers use to decide which inbound opportunities should be reviewed first, routed to which underwriter, and handled with what level of effort. In commercial P&C, the submission stream is uneven by design. Some accounts arrive complete, clean, and within appetite. Others are missing critical fields, include inconsistent narratives, or require specialized expertise and extra time to validate. When volumes rise, the underwriting team faces a simple constraint: attention is finite. Prioritization becomes the mechanism that protects cycle time, service levels, and underwriting quality.

Modern prioritization is not just a queue. It is a set of decisions that shape portfolio outcomes. Which submissions get a fast quote can influence win rate. Which ones are delayed can influence broker relationships and retention. How quickly an underwriter sees a complex risk can influence loss ratio, because speed without clarity can lead to mispricing or missed exclusions. And how consistently decisions are made can influence governance, especially when automation is involved.

The best programs treat prioritization as part of underwriting strategy. They define what “good” looks like for the carrier today, then use structured data, external signals, and clear rules to move the right work to the right people at the right time. When done well, prioritization reduces wasted touch time, increases throughput, and supports better risk selection without compromising fairness or compliance.

What Submission Prioritization Means in P&C Underwriting and Why It Matters

In P&C underwriting, a submission is more than an application. It is a package of information, documents, and context that helps an insurer decide whether to offer terms, at what price, and under what conditions. Prioritization is the discipline of ordering and routing those packages to maximize business value while respecting operational constraints. It generally answers three questions: should we work this now, who should work it, and what level of diligence is appropriate at this stage.

Prioritization matters because underwriting is a funnel with multiple choke points. Intake teams must ingest documents, validate fields, and resolve inconsistencies. Underwriters must assess hazards, classify operations, determine coverage needs, and confirm loss history. Actuarial and pricing tools may require additional inputs. If every submission is treated as equal, high-quality accounts may get stuck behind incomplete or out-of-scope risks, leading to slower response times and missed opportunities.

It also matters because not all speed is equal. Fast responses are valuable when the submission is in appetite and information is sufficient to support a confident decision. Speed is risky when the file is complex, ambiguous, or missing key data. Prioritization enables differential handling: quick quote paths for straightforward risks, and structured escalation paths for submissions requiring specialist review, additional documentation, or deeper analysis.

Finally, prioritization supports consistency. In many organizations, the implicit prioritization happens in individual inboxes based on personal judgment, broker relationships, or what looks easiest. That approach can be uneven and difficult to audit. A modern approach makes the decision logic explicit, monitored, and improvable over time. The goal is not to remove judgment, but to focus judgment where it has the highest impact, while reducing low-value administrative work that does not improve risk decisions.

Core Inputs: Submission Data Quality, Completeness, and External Signals

Submission prioritization depends on inputs that indicate both business value and operational effort. The first set of inputs is submission data quality. Clean, structured fields such as class code, revenue, payroll, years in business, location of operations where relevant, and requested limits allow faster classification and pricing. Data quality also includes internal consistency. If a narrative describes manufacturing but the class code indicates retail, the file will likely require clarification and should be prioritized differently than a submission that aligns across fields.

Completeness is the second major input. Missing loss runs, unclear ownership structure, incomplete schedules, or absent safety documentation increase the time needed to reach a decision. Many underwriters mentally score completeness by asking: can I quote with confidence using what I have? Modern workflows operationalize that question by defining required elements for each line and segment, distinguishing between “quote-blocking” gaps and “nice-to-have” enrichment. Completeness signals are especially useful for triaging new business versus renewals, because renewals often have more historical data but may require up-to-date exposure changes.

The third input category is external signals. These are data points beyond the submission package that help confirm identity, clarify operations, and estimate hazard. Examples include business registries, industry classification sources, property and geospatial data for certain lines, catastrophe exposure indicators, claims and loss databases where permitted, and web-based signals that validate the nature of operations. External signals can also include behavioral indicators such as broker responsiveness, historical hit ratios, or prior submission outcomes, as long as their use is governed and appropriate.

A key practical insight is that not every signal should change priority. Some signals should trigger verification rather than acceleration. For example, a discrepancy between reported revenue and external estimates might not mean the risk is bad, but it suggests the file needs attention before quoting. Likewise, a class ambiguity might indicate the need for a quick clarification call rather than an outright deprioritization. The best prioritization systems distinguish between “fast lane” eligibility signals and “hold and clarify” signals, because both improve throughput and quality when routed correctly.

Common Prioritization Methods: Triage Rules, Scoring Models, and Appetite Alignment

Most carriers use a combination of triage rules, scoring models, and appetite alignment to prioritize. Triage rules are the simplest and often the most effective starting point. They route submissions based on clear criteria such as line of business, minimum premium, territory or location of exposure where relevant, class of business, or required attachments. Rules can quickly separate submissions into buckets: auto-decline due to hard appetite constraints, request-more-information due to missing critical items, and ready-for-underwriter review. The strength of rules is transparency. The weakness is rigidity, especially when operations are nuanced.

Scoring models add flexibility by producing a numeric or tiered priority score that reflects expected value and expected effort. Value components might include estimated premium, likelihood of bind, strategic segment fit, or broker performance. Effort components might include complexity indicators like multi-state operations where relevant, multiple locations, unusual coverage requests, or high documentation burden. A practical approach is to separate these into two scores: desirability and friction. High desirability and low friction goes to the fast lane. High desirability and high friction goes to a senior underwriter or a specialist team with time blocked for complex work. Low desirability and high friction may be deprioritized or declined quickly to protect capacity.

Appetite alignment is the underwriting strategy layer. A carrier’s appetite is not only a list of eligible classes. It includes preferred risk characteristics, target account sizes, and risk controls that correlate with performance. Prioritization should mirror current appetite, which may shift based on reinsurance costs, portfolio concentration, or market conditions. If appetite tightens for a segment, priority logic should reflect that change immediately, otherwise underwriters will spend time on submissions that are unlikely to be written.

Operationally, modern teams implement prioritization as a routing workflow rather than a static queue. Submissions can change priority as new information arrives. A file that starts incomplete can move up once required documents are received. A risk that appears straightforward can be escalated when an external signal reveals higher hazard. This dynamic approach reduces rework and helps underwriters maintain momentum.

Another practical method is service-level prioritization. Some organizations commit to response times by segment, such as same-day indication for small, clean accounts. The key is to define response time promises that match actual capacity and to ensure that prioritization logic enforces those promises consistently, rather than relying on heroic effort.

Governance and Legal Considerations: Documentation, Fairness, Privacy, and Auditability

Submission prioritization touches regulated underwriting decisions and must be governed accordingly. Even when prioritization does not directly set price or coverage, it affects access to timely quotes and can create disparate outcomes if not managed carefully. Governance starts with documentation. Carriers should clearly document what signals are used, why they are used, and how they influence routing or timing. This includes version control, because appetite and models evolve. Without a record of what logic was active at a given time, it becomes difficult to explain outcomes to internal stakeholders, regulators, or auditors.

Fairness is a practical and ethical concern. Prioritization criteria should be tied to legitimate business objectives like risk suitability, completeness, and operational efficiency. Inputs that can proxy for protected characteristics, or that reflect non-risk factors inappropriately, should be avoided or carefully evaluated. For example, a model that heavily weights broker size might systematically delay smaller brokers regardless of risk quality, which can create relationship and reputational risks. Fairness reviews should include testing for disparate impact where relevant, and monitoring should be ongoing rather than one-time.

Privacy and data minimization matter when external data is used. Only collect and retain data necessary for underwriting purposes, and ensure the organization has a lawful basis and contractual rights to use third-party sources. Controls should specify who can access sensitive data, how long it is retained, and how it is secured. If automated extraction is applied to documents, organizations should also consider how they handle incidental personal information that may appear in submissions.

Auditability is essential as automation increases. Automated prioritization should produce explainable outputs. Underwriters and operations leaders need to know why a submission was routed or delayed. This is especially important for machine learning models, where explainability can be harder. Practical auditability includes logging key inputs, the decision rule or model version, and any human overrides. Overrides should be encouraged when appropriate, but they should be captured with reasons so the organization can learn whether the logic needs refinement or whether behavior is drifting.

Finally, governance should define accountability. Someone must own prioritization policy, monitor performance metrics like cycle time and hit ratio, and coordinate updates across underwriting, operations, legal, and compliance. Prioritization is not a one-time implementation. It is a living control that should evolve with the portfolio and the market.

FAQs

How is submission prioritization different from underwriting appetite?

Underwriting appetite defines what kinds of risks an insurer is willing to write and under what general conditions. Submission prioritization determines how quickly and by whom a particular inbound opportunity is handled. A submission can be within appetite but still be deprioritized if it is incomplete, complex, or unlikely to bind based on current capacity. Conversely, a submission might be close to the edge of appetite but prioritized for quick review if it is strategically important, time-sensitive, or from a key distribution partner, assuming governance supports that approach. In practice, appetite is the boundary and prioritization is the traffic system inside that boundary. Good programs keep them aligned by updating routing logic whenever appetite changes, so underwriters spend their time on submissions that are both eligible and valuable to work right now.

What data elements most improve prioritization accuracy?

The highest-impact elements are those that reduce uncertainty early. Clear business classification, consistent operational descriptions, accurate exposure bases such as revenue or payroll, and complete loss history materially affect how much effort is needed to quote. Request details also matter: requested limits, deductibles, and effective dates help determine urgency and feasibility. Document completeness is equally important, especially when schedules or supplemental applications are required for certain classes. External validation signals can improve accuracy when they confirm identity and operations or highlight inconsistencies that need clarification. The biggest practical improvement often comes from standardizing required fields by segment and defining what constitutes “quote-ready” versus “needs follow-up,” then measuring how those definitions correlate with cycle time and bind outcomes.

Does prioritizing submissions create fairness or discrimination risks?

It can, especially if prioritization criteria are not tied to underwriting-relevant factors or if they indirectly disadvantage certain groups. Even when insurers do not use protected characteristics, some variables can act as proxies. For example, prioritizing based on broker tier or geographic convenience where location is not risk-relevant can create systematic delays for certain channels or communities. Fairness risk is also present if automation makes decisions opaque and difficult to challenge. Mitigation involves clear policy: prioritize using risk suitability, completeness, and operational efficiency factors; minimize use of variables that reflect status rather than risk; and conduct monitoring for uneven outcomes. Human override and escalation paths are important so that a submission is not effectively denied service due to a data glitch or model error. Good documentation and periodic reviews help demonstrate that prioritization supports legitimate business needs.

How do carriers balance speed with underwriting quality?

They separate speed into “fast when confident” and “slow when necessary.” The goal is not to quote everything quickly, but to reach good decisions quickly when the information supports it. Practical techniques include creating a fast lane for clean, low-complexity submissions with standardized coverage requests; using completeness checks to prevent premature quoting; and routing complex accounts to specialists early rather than letting them bounce between desks. Carriers also use staged decisions, such as providing a quick indication or appetite response, followed by a deeper review before bind. Quality improves when underwriters spend less time chasing missing items and more time evaluating risk drivers. Measuring both cycle time and outcome quality, such as quote-to-bind and loss performance over time, helps ensure speed gains are not masking increased risk.

What should be logged for auditability in automated prioritization?

At minimum, the system should log the time date of receipt, key extracted or submitted fields used in prioritization, the decision outcome (for example, fast lane, request information, decline, specialist routing), and the specific rule set or model version applied. If external data sources are used, logs should note which sources were queried and what attributes were used, without storing unnecessary sensitive details. It is also important to log human interactions: when someone overrides a priority, who did it, and why. These logs support internal performance analysis and provide an evidence trail if decisions are questioned later. Auditability also benefits from storing “reason codes” that translate model outputs into understandable explanations, such as “missing loss runs” or “class ambiguity requiring review,” so that stakeholders can validate that the logic is behaving as intended.

Conclusion

Submission prioritization is a practical response to a real constraint in commercial P&C underwriting: there is more inbound opportunity than there is immediate underwriting attention. Done informally, prioritization becomes inconsistent and difficult to manage. Done intentionally, it becomes a strategic lever that improves responsiveness, protects underwriting quality, and aligns daily work with appetite and portfolio goals.

Effective prioritization starts with strong inputs, especially data quality and completeness, then incorporates external signals to validate and enrich the risk picture. From there, carriers typically combine transparent triage rules with scoring models that balance expected value against expected effort. The most resilient approaches are dynamic, allowing a submission’s priority to change as new information arrives, and operational, routing work to the right expertise instead of simply reordering a queue.

Because prioritization affects who gets timely service, governance matters. Documentation, fairness testing, privacy controls, and audit-ready logs are not extra work. They are safeguards that help underwriting teams innovate responsibly while maintaining trust.

To explore how modern underwriting teams implement scalable prioritization through modular AI underwriting workflows, data enrichment, and intelligent document automation, visit https://convr.com/.

blogs

Keep Reading

More articles on AI, underwriting and the future of commercial P&C.

XX MIN READ

Convr Prioritizes Communication in Underwriting Workbench

Email

Convr is making it easier than ever to communicate about submissions within the Convr AI Underwriting Workbench. Now there is an email capability where Convr customers can create new messages for submissions. A user would first need to have a specific submission open within the platform to see the email functionality available to them.

Within the left-hand pane they would just need to click, “Email” then “Create New Message.”

From there the “From” section will automatically be generated with their user email and they would need to plug in a recipient email address. The subject line would also be prepopulated with the submission name.

Convr users can also upload submissions assets and additional attachments about the submission in addition to crafting a customized message about the submission.

Comments
Within the Summary screen you can now also add a “Comment” about a submission, and they can be posted anywhere into Forms, Assets, Emails, etc. to support collaboration. Additionally, you can build a thread of comments. You can also reply to your own comment or react to another user’s comment with a thumbs up, as well.

The idea is that you’re creating a record or recorded conversation allowing another user to enter the platform, to get up to speed on the submission chat and join the conversation with the addition of new comments, which will show up within the feed as well.

You can tag users too, so they receive an in-app notification and email. You can also see in-app alerts, click on them and be taken directly to where you as a user were mentioned within the submission. This global, in-app notification feature is useful if a user wants to bring a team member’s attention to a given item within a submission.


The intent is to open lines of communication between underwriting team members to ensure there is greater transparency and oversight of submissions.

Convr is invested in improving the Convr AI Underwriting Workbench user interface for customers and believes these two new communication features will enhance collaboration and visibility throughout the submission process.  
 

To learn more about Emails and Comments capabilities reach out to Convr at convr.com to book a demo.

XX MIN READ

Agentic AI Doesn’t Just Assist, It Acts

For most of its early history, the Artificial Intelligence (AI) that was used in commercial P&C insurance was a co-pilot. It was an always-on analyst sitting beside the underwriting team surfacing data, flagging anomalies, organizing submissions and more. It was genuinely valuable, yet it still relied on a human to make the call.

Agentic AI changes that equation entirely. It doesn't wait for a prompt or pass-back to a human for every decision. It perceives, reasons, decides, and acts autonomously, within defined parameters, at an unmatched speed and scale. With Agentic AI and the organizational shift from AI experimentation to real‑world execution, new challenges are emerging. If Agentic AI systems are making decisions and taking actions, insurance underwriting teams need to be ready. That means new roles and levels of authority need to be defined. That way, Agentic AI agents will operate within clear boundaries, stay anchored to trusted enterprise data, and scale confidently across the organization, so innovation accelerates without sacrificing governance and control.

The reason Agentic AI requires new operational control is specific to its potential independence of reasoning, decisioning and action. It’s collecting information and getting back to the underwriting team member(s) with a result or response. You're no longer just asking it a question, but giving it the autonomy to perform an action — giving it more authority to operate on your behalf.

When engaged via the Convr AI Underwriting Workbench, your organization benefits from the power of  this reasoning capability within an underwriting workflow. For example, it can act on your behalf sending emails back to a broker for more information. But better still, you benefit from the controls required to customize the workflows to your specific business and governance requirements.

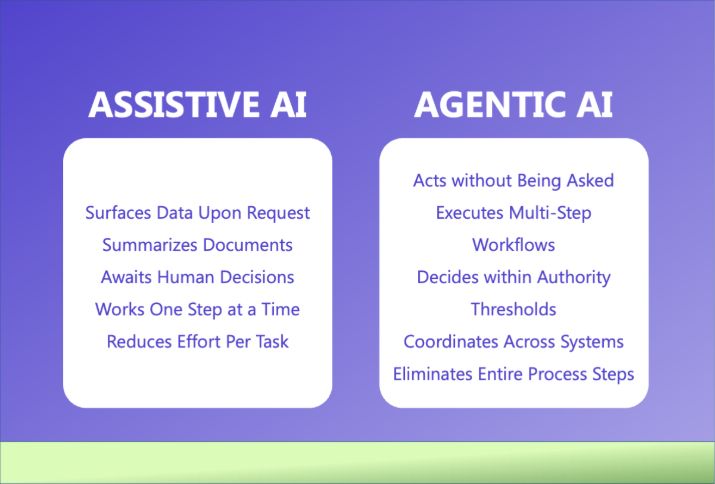
What separates Agentic AI from Assistive AI

Assistive AI is reactive. If you ask it a question, you’ll get an answer. If you feed it a commercial insurance underwriting submission, then you’ll get a summary. It’s powerful precisely because it reduces cognitive load — but the human remains in the loop at every decision point.

Agentic AI is proactive. It doesn't wait to be asked or given a prompt. Given a goal — clear a referral queue, flag a declination, prepare a financial analysis — an agentic system executes the full workflow: gathering relevant data, applying business logic, taking action, and reporting the outcome back to the underwriting team.

Here’s a helpful breakdown:


To learn more about Convr’s Agentic AI capabilities and what we’re doing for customers – get a demo now or read more about it on our newly revamped website at convr.com.


XX MIN READ

Why Agentic AI Needs Insurance-Specific Risk Context in Commercial Underwriting

Agentic AI has the potential to change commercial insurance underwriting by allowing artificial intelligence to do more than answer questions or summarize documents. AI agents can work toward defined objectives, gather information, use approved tools, evaluate conditions, and help move underwriting workflows forward.

But giving AI more autonomy introduces a fundamental challenge.

An AI system that can act needs to understand the context behind the information it is using.

Commercial P&C underwriting is not simply a document-processing problem. Underwriters make decisions based on relationships between businesses, locations, exposures, classifications, losses, coverages, limits, appetite rules, historical information, and external risk signals.

A general-purpose AI model may be highly capable at reading language while still lacking the specialized commercial insurance knowledge required to interpret those relationships reliably.

This is why insurance-specific risk context is becoming increasingly important as carriers and MGAs explore generative AI, AI agents, and more autonomous underwriting workflows.

The question for underwriting leaders is no longer simply:

Which AI model should we use?

A more important question is:

What information and insurance context is that model grounded in when it supports an underwriting decision?

What Is Insurance-Specific Risk Context?

Insurance-specific risk context is the structured information that helps an AI system understand what commercial insurance data means and how different pieces of information relate to one another.

A commercial submission might contain:

  • Named insured information
  • Business descriptions
  • Industry classifications
  • Revenue
  • Payroll
  • Locations
  • Property characteristics
  • Vehicles
  • Employees
  • Loss history
  • Limits
  • Coverages
  • Supplemental risk information

Simply extracting these values does not necessarily create underwriting intelligence.

The system also needs to understand the relationships between them.

For example, an address might represent:

  • Corporate headquarters
  • A mailing address
  • An insured property
  • A warehouse
  • A manufacturing location
  • A construction project

Those distinctions can materially affect the underwriting analysis.

Similarly, a loss record only becomes useful when the system understands which insured, location, exposure, and policy period it relates to.

Insurance-specific context gives AI the structure required to interpret those relationships.

Why General-Purpose AI Is Not Enough for Commercial Underwriting

General-purpose large language models are trained to understand and generate language across an enormous range of subjects.

That makes them powerful tools for:

  • Summarization
  • Drafting
  • Search
  • Question answering
  • Document interpretation
  • Conversational interfaces

However, fluency should not be confused with underwriting expertise.

Commercial underwriting contains specialized terminology, classifications, data structures, and relationships that may not be obvious from the text alone.

Consider a submission describing a business as:

Commercial painting contractor.

A general-purpose AI model may understand what painting is.

An underwriting system may need to understand considerably more:

  • Does the business perform interior or exterior work?
  • Does it work at height?
  • Does it perform industrial painting?
  • Does it work on bridges or infrastructure?
  • Are employees using scaffolding?
  • Does it subcontract work?
  • Which classification is appropriate?
  • Which exposures matter for the requested coverage?

These questions require insurance context.

The model needs more than a dictionary definition of the business.

It needs to understand how that business description connects to commercial P&C risk evaluation.

Convr’s current Risk Context Engine positioning reflects this distinction. The company describes its RCE as a commercial P&C-specific knowledge graph and semantic ontology designed to ground AI underwriting in structured insurance context rather than relying solely on general-purpose model inference. (convr.com)

Agentic AI Raises the Importance of Context

The need for contextual grounding becomes more important as AI takes on a more active role.

Consider two uses of AI.

AI Assistant

An underwriter asks:

Summarize the information in this submission.

The AI produces a summary.

The underwriter reviews it and decides what to do next.

AI Agent

The agent is given an objective:

Evaluate whether this submission fits appetite and determine the appropriate next workflow step.

The AI may need to:

  1. Interpret the submission.
  1. Identify the business.
  1. Determine relevant exposures.
  1. Gather additional information.
  1. Compare the risk against underwriting criteria.
  1. Identify missing data.
  1. Determine whether referral is required.
  1. Route the account.

The second scenario carries more responsibility.

The AI is not merely producing text.

It is using information to influence what happens next.

If the underlying context is wrong, the workflow decision can also be wrong.

Agentic AI Needs Grounding, Not Just Intelligence

Grounding connects an AI system to trusted information that can support its responses and actions.

For underwriting, grounding may include:

  • Original submission documents
  • Structured risk information
  • Carrier guidelines
  • Internal underwriting data
  • Historical account information
  • Approved external data
  • Classification structures
  • Authority rules
  • Insurance-specific knowledge models

Without grounding, the AI may rely too heavily on general model knowledge or inference.

That creates a problem because underwriting decisions frequently depend on organization-specific information.

An AI agent should not invent a carrier’s appetite.

It should use the actual appetite criteria it has been authorized to access.

It should not guess which exposure applies to a particular location.

It should use structured information that connects the location with the relevant risk.

It should not assume a requested limit falls within an underwriter’s authority.

It should evaluate the applicable authority rules.

Grounding turns an AI model from a general source of language intelligence into a tool capable of operating within a specific underwriting environment.

What Is a Knowledge Graph in Commercial Insurance?

A knowledge graph represents information as connected entities and relationships.

Instead of storing every piece of information as an isolated field, a graph can show how information relates.

A simplified commercial risk might contain relationships such as:

Named Insured

Operates

Business Activity

At

Location

Associated With

Exposure

Losses, policies, classifications, and other information can also be connected to the appropriate entities.

This structure is useful for AI because commercial underwriting depends heavily on relationships.

An underwriter does not simply ask:

What addresses appear in the submission?

They need to know:

Which locations represent insured exposures?

They do not simply ask:

What losses exist?

They need to understand:

Which operations or exposures generated those losses?

A knowledge graph can help preserve that context.

Convr currently positions its Risk Context Engine around this architecture, combining a commercial P&C knowledge graph, ontology, schema, and semantic layer to create a normalized view of risk information used across its underwriting capabilities. (convr.com)

What Is an Insurance Ontology?

An ontology defines concepts and relationships within a particular domain.

For commercial insurance, that domain may include concepts such as:

  • Business
  • Insured
  • Exposure
  • Location
  • Classification
  • Loss
  • Coverage
  • Limit
  • Building
  • Vehicle
  • Employee

The ontology helps the system understand what those concepts represent and how they relate.

This becomes particularly useful when different data sources describe the same thing differently.

For example, one source might use:

Annual sales

while another uses:

Annual revenue

The system needs to determine whether those fields represent the same concept within the underwriting context.

Similarly, multiple classification systems may describe a business using different codes or terminology.

A domain-specific ontology can help normalize those differences into a more consistent representation.

Semantic Understanding Helps Connect Fragmented Submission Data

Commercial insurance data rarely arrives through one clean database.

A submission may include:

  • PDFs
  • Emails
  • Spreadsheets
  • ACORD forms
  • Loss runs
  • Statements of values
  • Supplemental applications
  • Third-party data

The same risk may be represented differently across those sources.

A semantic layer helps connect information based on its meaning rather than relying only on identical field names.

This matters because an AI agent may need to evaluate information from several sources before determining what should happen next.

If the data remains fragmented, the AI risks treating related information as separate facts or failing to identify important relationships.

Convr’s underwriting architecture unifies structured and unstructured submission data into a normalized commercial insurance model, which then supports AI, analytics, and underwriting workflows. (convr.com)

Risk Context Can Help Detect Conflicting Information

Grounding is not only about finding information.

It can also help identify when information disagrees.

Suppose a submission contains:

Application revenue: $15 million

Financial statement revenue: $22 million

A simple extraction system might successfully extract both values.

But the underwriting problem is not extraction.

The problem is determining that there is a discrepancy that may need investigation.

The same issue can occur when:

  • Business descriptions differ
  • Named insureds do not match
  • Locations appear inconsistently
  • Classifications conflict
  • Loss totals differ
  • Employee counts vary between sources

An AI system with stronger contextual understanding can surface these conflicts rather than simply presenting multiple values.

That allows the workflow to pause or escalate when information needs human review.

Traceability Matters as AI Becomes More Autonomous

If an AI system only generates an internal summary, an underwriter can independently verify the information.

If the system begins influencing triage, referrals, appetite decisions, or workflow routing, traceability becomes much more important.

The user should be able to determine:

  • Where the information came from
  • Which source contained it
  • Which data point influenced the action
  • Which rule was applied
  • Why the system reached its conclusion

For example, an AI agent might state:

Referral required because the requested limit exceeds configured authority.

The underwriting team should be able to inspect:

  • The requested limit
  • Its original source
  • The applicable authority threshold
  • The workflow rule
  • The resulting action

That is very different from receiving an unexplained recommendation from a black-box model.

Convr’s RCE and MCP positioning emphasizes this concept by making underwriting context available to AI agents while preserving source traceability for the information returned. (convr.com)

Explainability and Traceability Are Not the Same Thing

These concepts are related but distinct.

Explainability

Explains why the system reached a conclusion.

For example:

This risk requires additional review because the exposure falls outside standard appetite criteria.

Traceability

Shows the information that supports that conclusion.

For example:

  • Original business description
  • Classification
  • Exposure information
  • Applicable appetite rule
  • Source document

An AI system may produce a convincing explanation without having strong traceability.

For underwriting organizations, both matter.

The conclusion should make sense, and users should be able to inspect the evidence behind it.

Insurance-Specific Context Can Support More Consistent Decisions

Commercial carriers often have large underwriting teams operating across:

  • Regions
  • Offices
  • Distribution channels
  • Lines of business
  • Experience levels

Two underwriters can interpret the same information differently.

Human judgment is an important part of underwriting, but inconsistency in routine data interpretation or guideline application can create unnecessary variability.

Insurance-specific AI can help create a more consistent foundation.

For example, the system can help ensure that:

  • The same risk data is interpreted consistently
  • Classifications are evaluated against the same framework
  • Relevant information is surfaced systematically
  • Mandatory referral conditions are checked
  • Source information is preserved

The goal is not to eliminate underwriting judgment.

It is to give underwriters a more consistent information layer on which to apply that judgment.

The Underwriter Still Owns the Decision

A stronger contextual foundation does not mean every underwriting decision should become autonomous.

Commercial risks can involve nuance that is difficult to reduce to a universal set of rules.

An experienced underwriter may consider:

  • Broker knowledge
  • Management quality
  • Loss explanations
  • Risk controls
  • Market conditions
  • Strategic account value
  • Coverage structure
  • Pricing considerations

Insurance-specific AI can organize the evidence and automate repeatable checks.

The underwriter can then focus on interpreting what the evidence means.

This represents an important principle for agentic underwriting.

The more effectively technology manages context, data gathering, and repeatable workflow decisions, the more attention human underwriters can give to the areas where professional judgment creates the greatest value.

AI Grounding Is Becoming an Underwriting Infrastructure Question

As insurers evaluate AI, attention naturally goes to the models themselves.

Which model is most accurate?

Which model is fastest?

Which model can handle the largest documents?

Those questions matter.

But commercial underwriting AI also depends on what surrounds the model.

Underwriting leaders increasingly need to consider whether their AI environment can:

  • Understand insurance concepts
  • Preserve relationships between risk information
  • Normalize fragmented submission data
  • Connect to approved sources
  • Apply carrier-specific rules
  • Trace information to its origin
  • Support controlled workflow actions

Without those capabilities, increasing AI autonomy may simply increase the speed at which uncertain information moves through the underwriting process.

With the right risk context, agentic AI has the potential to become something much more valuable: a governed decision-support layer that understands the commercial insurance environment in which it is operating.

What Insurance-Specific Context Changes in Practice

Insurance-specific context changes what AI can do with underwriting information.

A general model may be able to summarize a submission. A context-aware underwriting system can connect that information to the concepts, rules, and relationships that matter for the risk.

That can improve several parts of the workflow.

Submission Triage

The system can identify missing information, evaluate whether a submission appears to fit appetite, and determine whether it should proceed, stop, or be escalated.

Risk Enrichment

External information can be connected to the correct insured, location, operation, or exposure rather than added as disconnected data.

Guideline Application

Carrier-specific rules can be evaluated against structured risk information instead of relying on a model to infer what the organization considers acceptable.

Referral Preparation

The system can identify the relevant trigger, gather supporting evidence, and prepare information for human review.

The more active AI becomes in the workflow, the more important this context becomes.

Context Can Help Reduce Hallucination Risk

One of the best-known risks of generative AI is hallucination, where a model produces information that sounds plausible but is unsupported or incorrect.

In underwriting, a model should not invent:

  • A business classification
  • A loss event
  • A property characteristic
  • An appetite rule
  • An authority threshold

Grounding helps reduce this risk by directing the AI toward trusted underwriting information.

It does not remove the need for governance or human review. It gives the model a stronger evidence base.

For underwriting leaders, the key question is not whether AI can produce a convincing answer.

It is whether the answer can be tied back to trusted commercial insurance data and the rules governing the decision.

Source Lineage Supports Better Governance

Source lineage preserves the connection between a data point and where it originated.

If an underwriter reviews a location-level exposure, they may need to know whether the value came from:

  • The application
  • A statement of values
  • A prior policy record
  • An external data source
  • A manually entered field

If sources disagree, lineage helps the underwriter understand the conflict.

As AI agents become more involved in referrals, routing, appetite checks, and other workflow decisions, source lineage also makes those actions easier to review and audit.

Context Should Travel With the AI Workflow

Insurance-specific context should not exist inside one isolated application.

Carriers may use several AI models, assistants, and agents across underwriting.

A stronger approach is to make trusted risk context available wherever approved AI workflows need it.

That could include:

  • Underwriting workbenches
  • Internal AI assistants
  • Agentic workflows
  • Portfolio analytics
  • Decision-support tools

If several AI systems are evaluating the same account, they should not each reconstruct the risk independently from fragmented source documents.

A shared contextual layer can provide a more consistent understanding of the insured and its exposures.

Model Flexibility Matters

The AI model landscape is changing quickly.

Carriers may use different models for different tasks or change providers as capabilities improve.

The commercial insurance context, data relationships, underwriting rules, and source lineage should remain valuable even when the underlying model changes.

The model can provide reasoning and language capabilities.

The underwriting context provides the domain-specific knowledge that makes those capabilities useful.

This creates a more durable AI architecture than tying underwriting intelligence to one model alone.

Human-AI Collaboration Improves When Evidence Is Visible

Insurance-specific context can also improve the underwriter experience.

An underwriter may ask:

Why was this account referred?

A context-aware system should be able to identify the relevant rule and the information that triggered it.

The underwriter might then ask:

Which source provided that value?

The system should be able to show the supporting evidence.

This makes AI easier to challenge, validate, and trust.

The goal is not to remove underwriting judgment. It is to give underwriters stronger information and reduce the manual work required to reach a decision.

A Practical Roadmap for Context-Aware Agentic AI

Underwriting organizations can approach agentic AI in stages:

  1. Identify trusted sources for important underwriting information.
  1. Normalize concepts such as insureds, locations, exposures, losses, classifications, and coverages.
  1. Connect the relationships between those entities.
  1. Preserve source lineage back to the original information.
  1. Ground AI workflows in relevant risk context and carrier rules.
  1. Define which actions agents can take and which require human approval.
  1. Start with focused use cases such as triage, risk enrichment, referral preparation, or renewal review.
  1. Measure accuracy, speed, overrides, and underwriter trust before expanding autonomy.

This creates a more controlled path toward agentic underwriting than attempting to automate the entire underwriting process at once.

Frequently Asked Questions

Why does agentic AI need insurance-specific context?

Agentic AI needs insurance-specific context because commercial underwriting depends on specialized concepts and relationships between insureds, locations, exposures, losses, classifications, coverages, and carrier rules. General AI may understand the language without fully understanding its underwriting significance.

What is grounding in insurance AI?

Grounding connects an AI system to trusted underwriting information, such as submission data, carrier guidelines, internal risk information, approved external sources, and structured insurance knowledge. It helps responses and actions rely on evidence relevant to the insurer’s actual environment.

What is a knowledge graph in commercial insurance?

A commercial insurance knowledge graph represents businesses, locations, exposures, losses, policies, and other entities as connected information rather than isolated fields. This helps AI understand how different data points relate to the same commercial risk.

Can insurance-specific context reduce AI hallucinations?

Grounding AI in trusted insurance data can reduce unsupported outputs by giving the model a stronger evidence base. It does not remove the need for validation, governance, or human oversight, particularly for material underwriting decisions.

Why is source lineage important for underwriting AI?

Source lineage allows underwriters to see where information originated and which evidence supported an AI recommendation or action. This helps resolve conflicting data, supports auditability, and builds trust in AI-assisted underwriting.

Give Agentic AI the Commercial Insurance Context It Needs With Convr

The future of underwriting AI will not be determined by model capability alone.

Commercial insurers need AI systems that can understand the structure of commercial risk, connect fragmented information, preserve source lineage, apply relevant underwriting context, and operate within governed workflows.

That foundation becomes even more important as organizations move from generative AI assistants toward agentic systems that can recommend or take actions.

Convr is built specifically for commercial P&C underwriting. Its Risk Context Engine provides an insurance-specific foundation for structuring, connecting, and contextualizing risk information so AI-powered underwriting workflows can operate with stronger grounding and traceability.

For carriers and MGAs exploring agentic underwriting, the priority should be more than giving AI greater autonomy. It should be giving AI the right commercial insurance context before that autonomy expands.

Explore Convr to see how its AI-powered underwriting platform can support more intelligent, traceable, and context-aware underwriting workflows.

Realize End-to-End Underwriting Excellence with Convr AI

Experience how commercial P&C insurance organizations benefit from submission through quote with a frictionless process enriched by AI decisioning, empowering them to make better decisions, faster.